You type a question, and in under a second Google hands you ten blue links — usually the right answer. It feels like magic, but it is engineering. So how do search engines work? Here is the surprising truth: when you search, Google does not search the internet. It searches its own copy of it — a vast library built in advance and updated constantly. That one fact explains almost everything else about search.
The Big Idea: A Search Engine Searches Its Own Copy
A search engine is, at heart, a stored copy of the web plus an opinion about it. Long before you type your query, the engine has already visited billions of pages, read them, and filed away what each one says in a giant database called the index. Your query never travels out across the web: it goes to one company's data centre, is matched against that company's copy of the web, and comes back ordered by its judgement about which pages are worth showing first.
That is why search is so fast — looking up a pre-built index takes milliseconds, while searching the live internet for every query would take minutes. Google holds about 89.94% of the worldwide search market (September 2026), so most of this guide follows Google's own documentation, though Bing and other engines run the same basic pipeline.
Every search engine runs the same three-stage pipeline, in order:
- Crawling — finding and fetching pages
- Indexing — understanding and storing them
- Ranking — choosing the best matches when someone searches
Step 1: Crawling — Finding the Pages
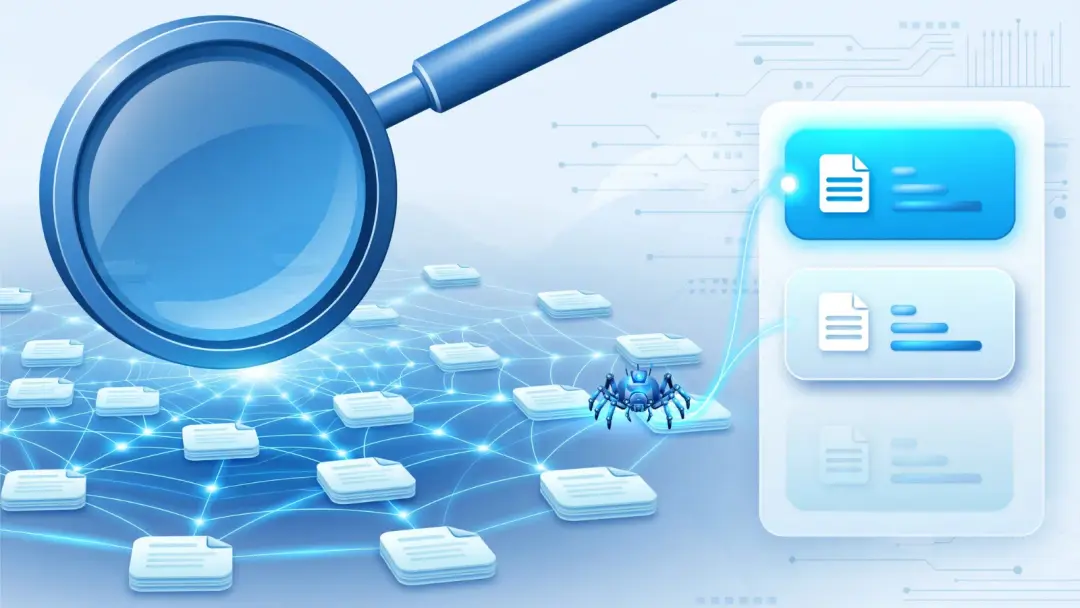
A crawler — also called a spider or a bot — is a program that requests a web page exactly as a browser would, stores what comes back, extracts the links on that page, and adds the new URLs to a queue. Google's crawler is called Googlebot (Smartphone and Desktop variants, since Google indexes the mobile version of pages first); Bing's is called Bingbot.
How does a crawler find a page in the first place? Google says it has no central registry of the web: it discovers URLs by following links from pages it already knows, and from sitemaps — files that website owners submit listing their pages. New sites need links pointing to them, or a submitted sitemap, before they can be found at all.
Crawling can fail. A site can block the crawler in a file called robots.txt; a page can return a server error; a page with no links pointing to it may simply never be discovered. Plenty of pages never make it past this first step. To see what happens before a page even reaches a search engine, read our guide to how the internet actually works.
Step 2: Indexing — Filing Everything Away
Once a page is crawled, the engine analyses it — what it says, what language it is in, which words matter, and whether it duplicates another page — then stores the result in the index.
The index is not a pile of whole pages. It is an inverted index: instead of a list of pages each containing words, the engine stores a list of words, each pointing to every page that contains it, with positions and weights attached. That inversion is what makes a search across billions of pages answerable in milliseconds.
Two important details. First, the engine groups similar pages and picks one canonical version to show — if the same article exists at three URLs, only one of them can rank. Second, Google is clear that not every page it crawls gets indexed: low-quality, thin or duplicate content is crawled and discarded. The engine also has to render pages — run their JavaScript — before it can fully understand them, which is why heavy, slow pages can struggle.
Step 3: Ranking — Choosing What to Show First
Ranking is where search engines genuinely differ, and it is the part users care about most. When your query arrives, the engine pulls candidate pages from the index, scores them, and shows the highest scorers in order.
The famous starting point is PageRank, the method Larry Page and Sergey Brin published while at Stanford in the 1990s: a link to a page counts as a vote for it, and a vote from an important page counts more than one from an obscure page. Modern ranking builds far beyond that. Google's published systems include BERT and RankBrain, neural networks that understand how words relate to concepts and to the intent behind a query — so "how to fix a leaking tap" returns repair guides, not plumbing adverts.
Google says ranking weighs hundreds of signals, including:
- Relevance — does the page actually match the query's words and intent?
- Quality — is the content original, trustworthy and useful?
- Links — do other reputable pages link to it?
- Freshness — for news and fast-moving topics, is it recent?
- Location, language and device — the same query returns different results in Lahore and London, on a phone and on a laptop.
- Spam detection — is the page trying to game the system?
One thing Google states plainly: it does not accept payment to crawl a site more often or to rank it higher. Organic ranking cannot be bought — only earned, which is why entire industries exist around making pages genuinely more useful.
What About AI Answers?
The newest layer on top of search is the AI answer — Google's AI Overviews, Microsoft Copilot, ChatGPT search and similar tools that write a direct answer instead of listing links. These sit on top of the same indexes: a page that fails crawling or indexing cannot be cited by an AI answer either, so the old pipeline still decides what the new AI tools can say. Indexing matters more now, not less — the index is the raw material for every AI summary you read.
Why Some Pages Never Show Up
| Reason | What happens |
|---|---|
| Blocked by robots.txt | The crawler is told not to fetch the page at all |
| No links or sitemap entry | The page is never discovered |
| Thin or duplicate content | Crawled, but not indexed |
| Noindex tag | The owner deliberately keeps it out of the index |
| Server errors | The crawl fails and the page is skipped |
| Heavy JavaScript that won't render | The engine cannot fully read the page |
If you run a website, these are the six things to check first when a page is invisible in search. The engine's own tools — Google Search Console's URL Inspection, or Bing Webmaster Tools — will tell you exactly which stage a page failed at. Our guide to how DNS works covers the step that happens even before crawling: turning a domain name into an address the crawler can visit.
Takeaway Checklist
- Search engines search their own index, not the live internet — that is why results arrive in milliseconds.
- Crawling finds pages (Googlebot follows links and sitemaps); indexing files them away; ranking orders them.
- The index is an inverted index: words pointing to pages, not pages containing words.
- PageRank treats links as votes; modern systems like BERT and RankBrain add language understanding.
- Ranking weighs hundreds of signals — relevance, quality, links, freshness, location and spam detection.
- Not every crawled page is indexed — thin or duplicate content is discarded.
- AI answers sit on top of the same index, so a page that is not indexed cannot be cited.
- You cannot pay Google to rank higher — organic ranking has to be earned.